This tutorial walks you through a sample online feature store application with ScyllaDB Cloud.
After completing the project, you will be able to use ScyllaDB as a
feature store and integrate it with the Feast framework.
# about-feature-stores.md
# Why should you consider ScyllaDB as a feature store?
ScyllaDB is a real-time NoSQL database that is best suited for feature store use cases where you require **low latency** (e.g. model serving), **high throughout** (e.g. training) and need peta-byte scalability.
Feature store is a central data store to power operational machine learning models. They help you store transformed feature values in a scalable and performant database. Real-time inference requires features to be returned to applications with low latency at scale. This is where ScyllaDB can play a crucial role in your machine learning infrastructure.
[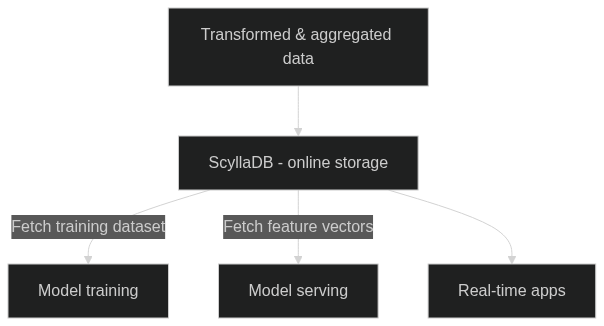](https://mermaid.live/edit#pako:eNptkLtuwzAMRX-F4NDJ_gEPBdq62bI0mWp7ICRaFqqHQckpgjj_XtVJOxTlxMe5xCUvqKJmbHB08VNNJBmObR-gxFN3FAppjOJZwwOQMcKGcik0ZRqgrh_hhr50B3V2jtpnqCEGZwNDylHIMAx3ZMPXHWc1QRaywQazLUqcV2i7ffHhfif_qUamvAjDiVXZnVZ4vYsSy-mvZte9Mbk6W89A85wGrNCzeLK6XHv5RnvME3vusSmpJvnosQ_XwtGS4-EcFDZZFq5wmYtPbi0ZIY_NSC6VLmtbbOxv79u-WOFM4T3GH-b6BaPtdAY)
What ScyllaDB brings to the table:
* **Low-latency**: ScyllaDB can provide <1 ms P99 latency. For real-time machine learning apps, an online feature store is required to meet strict latency requirements. ScyllaDB is an excellent choice for an online store (Read how [Medium is using ScyllaDB](https://medium.engineering/scylladb-implementation-lists-in-mediums-feature-store-part-2-905299c89392) as a feature store.)
* **High-throughput**: Training requires querying huge amounts of data and processing large datasets with possibly millions of operations per second - something that ScyllaDB excels at.
* **Large-scale**: ScyllaDB can handle petabytes of data while still keeping latency low and predictable.
* **High availability**: ScyllaDB is a highly available database. With its distributed architecture, ScyllaDB keeps your feature store database always up and running.
* **Easy to migration**: ScyllaDB is compatible with DynamoDB API and Cassandra which means it’s simple to migrate over from legacy solutions.
* **Integration with Feast**: ScyllaDB integrates well with the popular open-source feature store framework, Feast. Example architecture with Feast and ScyllaDB:
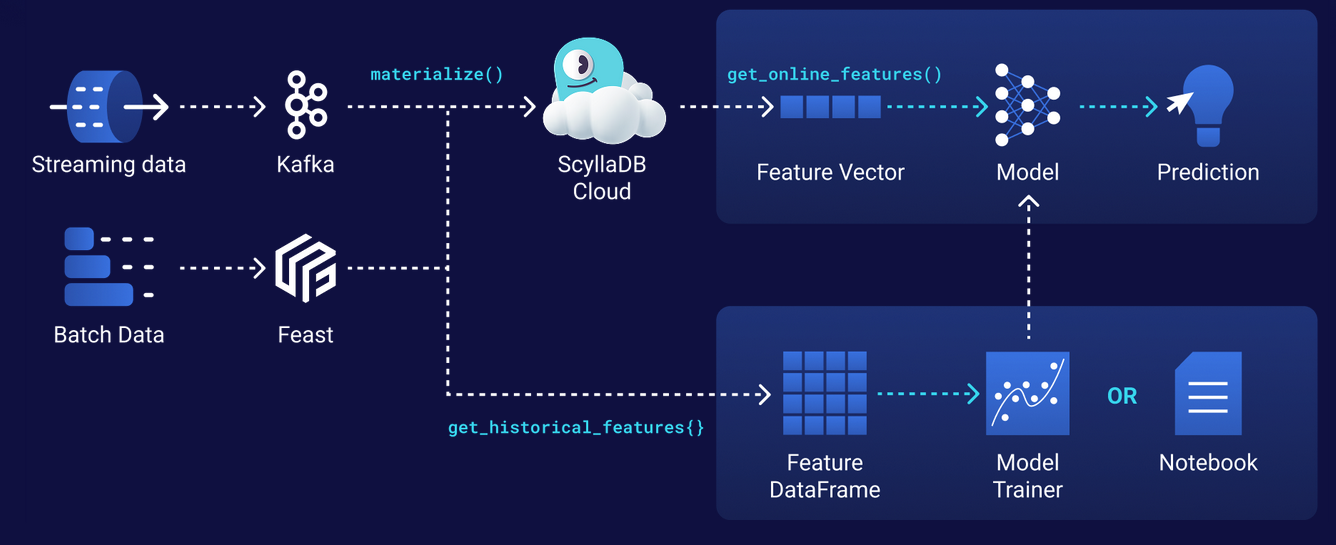
# credit-scoring-app.md
# Real-time credit scoring application with Feast & ScyllaDB
This repository is based on [this](https://github.com/feast-dev/feast-aws-credit-scoring-tutorial) existing Feast sample application.

This sample project is a real-time credit scoring application example that shows you how to set up Feast with ScyllaDB Cloud as an online store and parquet files as offline store.
## Requirements
* Python 3
* [ScyllaDB Cloud account](https://cloud.scylladb.com/)
## Get started
Clone the repository:
```default
git clone https://github.com/zseta/scylladb-feast
cd scylladb-feast
```
Project details:
* The primary training dataset is in `loan_table.parquet`. This file contains historic loan data with accompanying features. The dataset also contains a target variable, namely whether a user has defaulted on their loan.
* Feast is used during training to enrich the loan table with `zipcode` and `credit history` features from other parquet files.
* Feast is also used to serve the latest `zipcode` and `credit history` features for online credit scoring using ScyllaDB Cloud.
In this tutorial, you’ll do the following steps:
1. Create a new ScyllaDB Cloud cluster
2. Create a new keyspace for the feature store
3. Install dependencies and configure Feast
4. Deploy and test the feature store
## Create ScyllaDB Cloud cluster
Go to [ScyllaDB Cloud](https://cloud.scylladb.com/) and create a new cluster (either “Free Tial” or “Dedicated VM”). You can use the smallest available machine for this sample app (`t3.micro`)
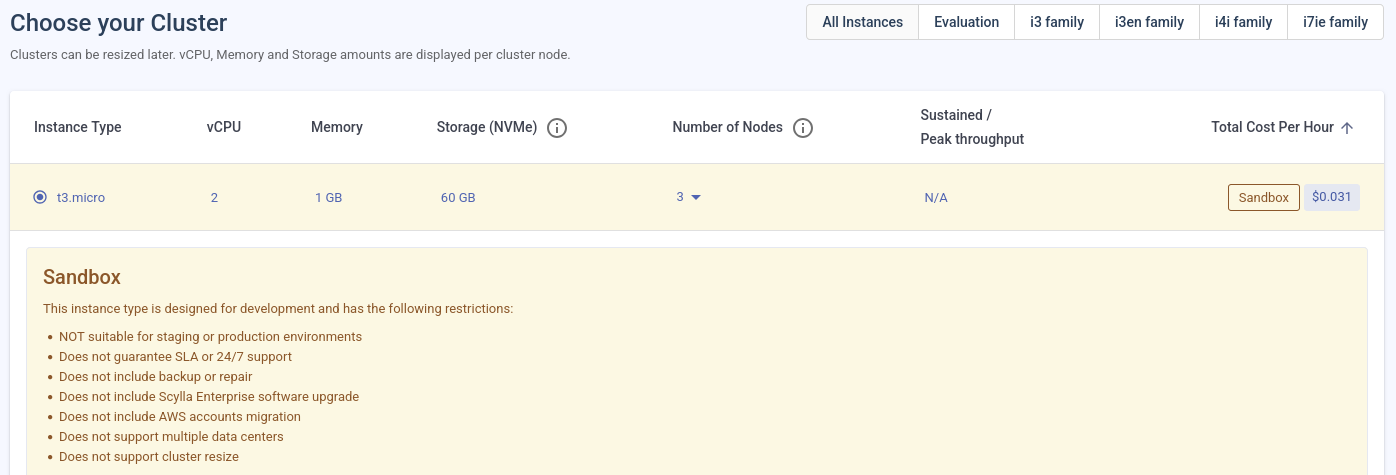
## Create new keyspace
Install CQLSH command line tool and connect to the ScyllaDB cluster:
```default
pip install cqlsh
cqlsh -u scylla -p
```
You can get the host address, username, and password from your ScyllaDB Cloud dashboard:
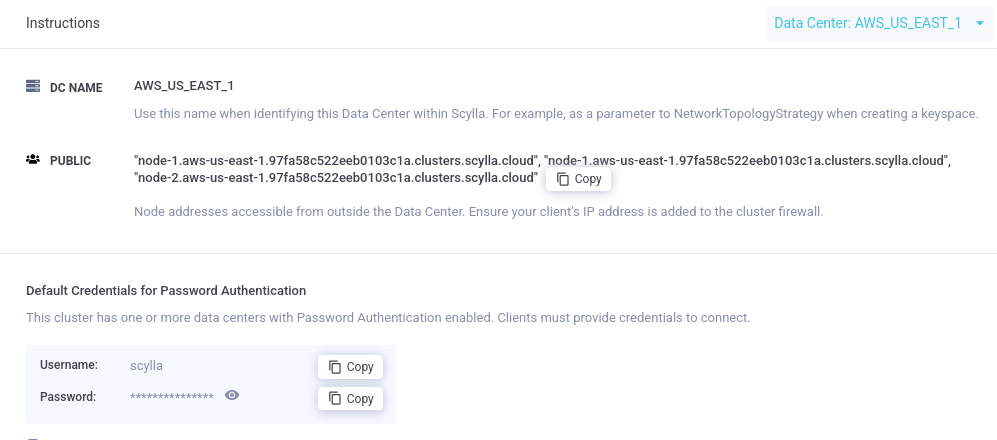
Create a new keyspace called `feast` in ScyllaDB (this keyspace will be populated by Feast):
```default
CREATE KEYSPACE feast WITH replication = {'class': 'NetworkTopologyStrategy', 'replication_factor': '3'} ;
```
## Install dependencies and configure Feast
Create a new Python environment and install dependencies:
```default
virtualenv env && source env/bin/activate
pip install -r requirements.txt
```
Next, configure ScyllaDB Cloud as the online store for Feast.
> [!TIP]
> Feast ships with a native ScyllaDB online store connector, so no extra setup beyond `pip install feast[scylladb]` is required.
Open the feature_store.yaml file and add the host addresses, username (`scylla`), password, and datacenter name for ScyllaDB:
```yaml
project: repo
# By default, the registry is a file (but can be turned into a more scalable SQL-backed registry)
registry: data/registry.db
# The provider primarily specifies default offline / online stores & storing the registry in a given cloud
provider: local
online_store:
type: scylladb
hosts:
- x.x.x.x
- x.x.x.x
- x.x.x.x
username: scylla
password: pass
keyspace: feast
local_dc: AWS_US_EAST_1
entity_key_serialization_version: 3
```
You can get the host addresses, username, and password from the ScyllaDB Cloud dashboard. `local_dc` should match the datacenter name of your cluster (visible in the ScyllaDB Cloud dashboard).
## Deploy and test the feature store
Deploy the feature store by running `apply` from within the `feature_repo/` folder
```default
cd feature_repo/
feast apply
Deploying infrastructure for credit_history
Deploying infrastructure for zipcode_features
```
This commmand also generates a `registry.db` file in your `data/` folder containing Feast configuration information.
Next, load features into the online store using the `materialize-incremental` command. This command loads the
latest feature values from a data source (parquet files, in our case) into the online store (ScyllaDB).
```default
CURRENT_TIME=$(date -u +"%Y-%m-%dT%H:%M:%S")
feast materialize-incremental $CURRENT_TIME
```
The loading process starts:
```default
35%|███████████████████▋ | 9965/28844 [01:20<02:39, 118.37it/s]
```
When it’s completed, train the model using `run.py` (in the root folder of the repository)
```default
cd ..
python run.py
```
The script returns the result of a single loan application:
```default
Loan rejected!
```
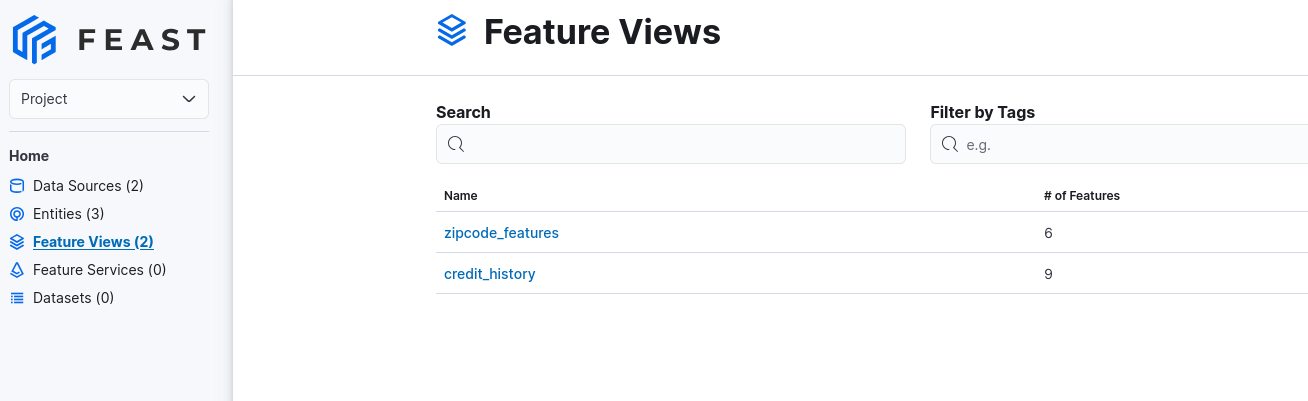
You can also run `feast ui` to explore your features:
```default
feast ui
```
Open http://0.0.0.0:8888
## Interactive demo
Run the Streamlit app locally:
```default
streamlit run app.py
```
Go to http://localhost:8501
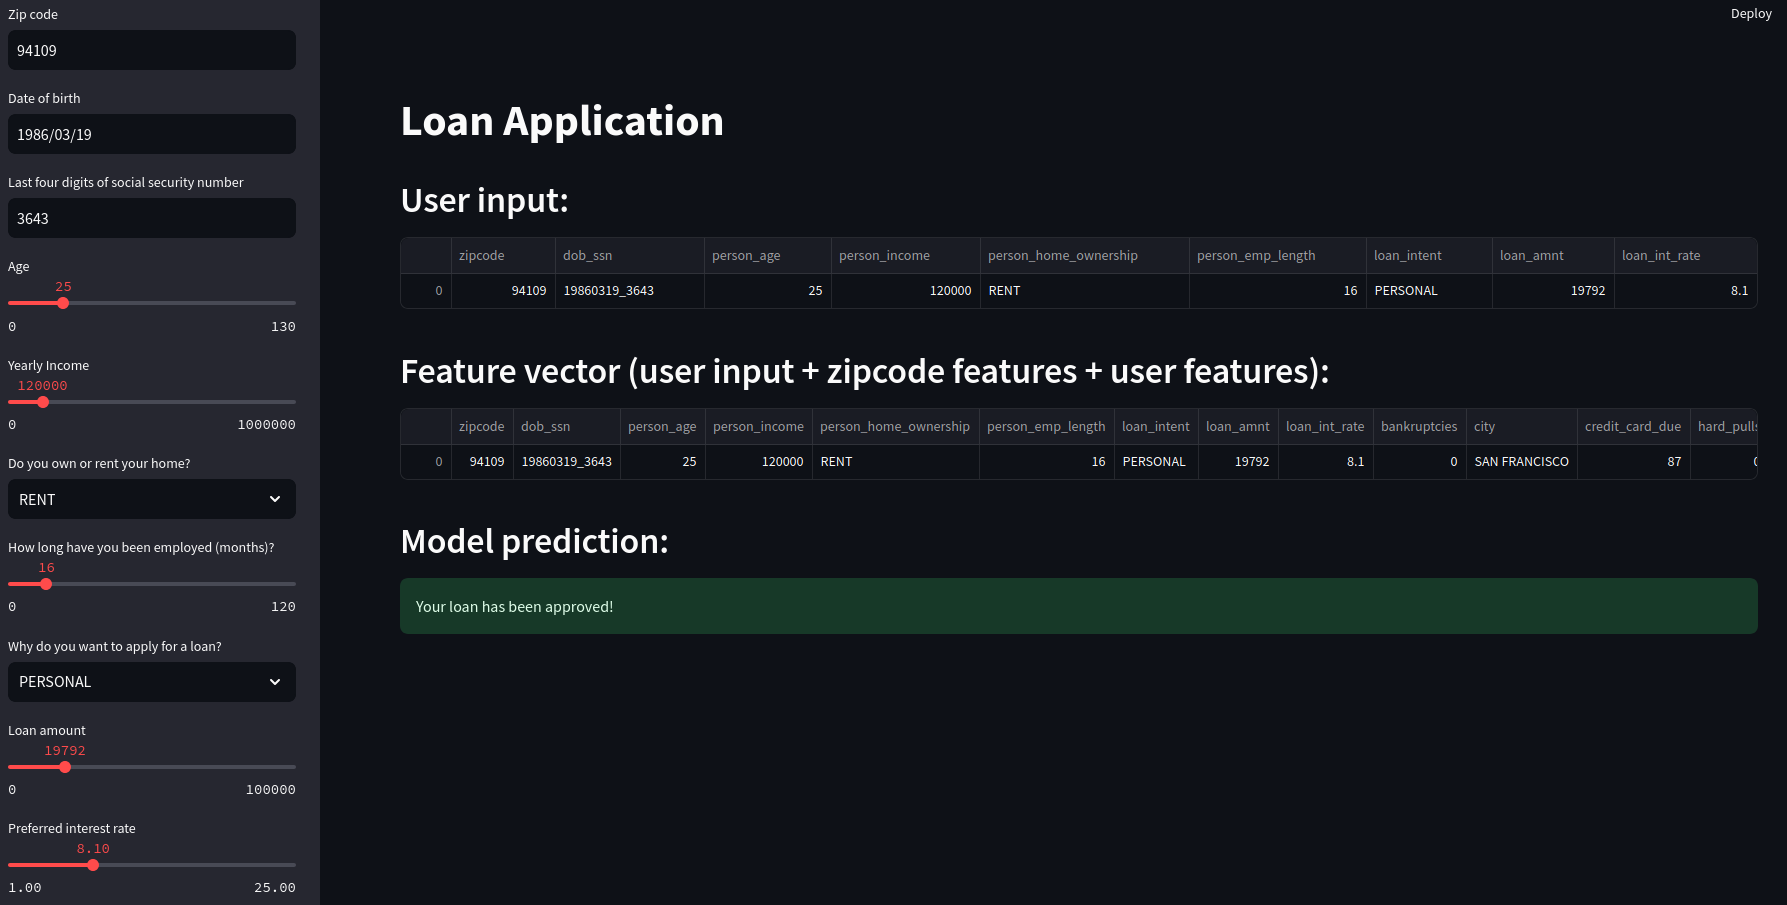
You can modify the variables on the left sidebar then the app will automatically run the prediction using the model.
# feast-scylladb-online-store.md
# Integrate ScyllaDB and Feast
[Feast](https://feast.dev/) is a popular open-source feature store for production ML. You can use several online stores when using Feast, including ScyllaDB. ScyllaDB, a low-latency and high-throughput database, serves perfectly as an online store. In this section, you’ll see how you can integrate your ScyllaDB Cloud database with Feast as an online store.
If you want to learn more about Feast, read the [Feast documentation](https://docs.feast.dev/).
## Feast + ScyllaDB online store configuration example
Feast ships with a native ScyllaDB online store connector, built on the `scylla-driver` Python package.
To set up ScyllaDB as a Feast online store you need to
1. Install Feast with the ScyllaDB extra
2. Edit the Feast configuration file
### Install Feast with the ScyllaDB extra
```default
pip install feast[scylladb]
```
### Edit the Feast configuration file
```yaml
# feature_store.yaml
project: repo
registry: data/registry.db
provider: local
online_store:
type: scylladb
hosts:
- node-0.aws_us_east_1.xxxxxxx.clusters.scylla.cloud
- node-1.aws_us_east_1.xxxxxxx.clusters.scylla.cloud
- node-2.aws_us_east_1.xxxxxxx.clusters.scylla.cloud
username: scylla
password: xxxxxxx
keyspace: feast
local_dc: AWS_US_EAST_1
entity_key_serialization_version: 3
```
Key configuration options for the `scylladb` online store:
* `hosts`: contact-point addresses of your cluster (required)
* `port`: CQL port (default: `9042`)
* `keyspace`: target keyspace (default: `feast_keyspace`)
* `username` / `password`: authentication credentials
* `local_dc`: datacenter name used for DC-aware load balancing (required for ScyllaDB Cloud, e.g. `AWS_US_EAST_1`)
* `read_concurrency` / `write_concurrency`: number of concurrent in-flight statements (default: `100` each)
* `vector_similarity_function`: default similarity function for vector search — `COSINE`, `DOT_PRODUCT`, or `EUCLIDEAN` (default: `COSINE`)
For more information, read the [Feast documentation](https://docs.feast.dev/reference/online-stores/scylladb).
# getting-started.md
# ScyllaDB for training data
This example project demonstrates a machine learning feature store use case for ScyllaDB.
You’ll set up a database with flight feature data and use ScyllaDB to train a model using decision tree classification.
## Clone the repository
```bash
git clone https://github.com/scylladb/scylladb-feature-store.git
```
## Sign up for a ScyllaDB Cloud account
To complete this project, sign up for a free trial account on [ScyllaDB Cloud](https://cloud.scylladb.com/user/signup). This is the easiest way to start using ScyllaDB.
If you prefer to use a self-hosted version of ScyllaDB, [see installation options here](https://www.scylladb.com/download/#open-source) (e.g. Docker).
## Prerequisites:
* [cqlsh](https://pypi.org/project/cqlsh/)
* [Python 3.7+](https://www.python.org/downloads/)
## Data model
Run the `schema.cql` file to create keyspace `feature_store` and table `flight_features`:
```bash
cqlsh "node-0.aws_us_east_1.xxxxxxxxx.clusters.scylla.cloud" 9042 -u scylla -p "password" -f schema.cql
```
This creates the following table in your database:
```sql
create table feature_store.flight_features(
FL_DATE TIMESTAMP,
OP_CARRIER TEXT,
OP_CARRIER_FL_NUM INT,
ORIGIN TEXT,
DEST TEXT,
CRS_DEP_TIME INT,
DEP_TIME FLOAT,
DEP_DELAY FLOAT,
TAXI_OUT FLOAT,
WHEELS_OFF FLOAT,
WHEELS_ON FLOAT,
TAXI_IN FLOAT,
CRS_ARR_TIME INT,
ARR_TIME FLOAT,
ARR_DELAY FLOAT,
CANCELLED FLOAT,
CANCELLATION_CODE TEXT,
DIVERTED FLOAT,
CRS_ELAPSED_TIME FLOAT,
ACTUAL_ELAPSED_TIME FLOAT,
AIR_TIME FLOAT,
DISTANCE FLOAT,
CARRIER_DELAY FLOAT,
WEATHER_DELAY FLOAT,
NAS_DELAY FLOAT,
SECURITY_DELAY FLOAT,
LATE_AIRCRAFT_DELAY FLOAT,
PRIMARY KEY (OP_CARRIER_FL_NUM)
);
```
## Import the dataset into ScyllaDB
```bash
cqlsh "node-0.aws_us_east_1.xxxxxxxxx.clusters.scylla.cloud" 9042 -u scylla -p "password"
scylla@cqlsh> COPY feature_store.flight_features FROM 'flight_features.csv';
```
This will start ingesting data into your ScyllaDB instance:
```default
op_carrier_fl_num|actual_elapsed_time|air_time|arr_delay|arr_time|cancellation_code|cancelled|carrier_delay|crs_arr_time|crs_dep_time|crs_elapsed_time|dep_delay|dep_time|dest|distance|diverted|fl_date |late_aircraft_delay|nas_delay|op_carrier|origin|security_delay|taxi_in|taxi_out|weather_delay|wheels_off|wheels_on|
-----------------+-------------------+--------+---------+--------+-----------------+---------+-------------+------------+------------+----------------+---------+--------+----+--------+--------+-------------------+-------------------+---------+----------+------+--------------+-------+--------+-------------+----------+---------+
4317| 96.0| 73.0| -19.0| 2113.0| | 0.0| | 2132| 2040| 112.0| -3.0| 2037.0|MLI | 373.0| 0.0|2018-12-31 02:00:00| | |OO |DTW | | 5.0| 18.0| | 2055.0| 2108.0|
3372| 94.0| 74.0| 81.0| 1500.0| | 0.0| 0.0| 1339| 1150| 109.0| 96.0| 1326.0|RNO | 564.0| 0.0|2018-12-31 02:00:00| 81.0| 0.0|OO |SEA | 0.0| 3.0| 17.0| 0.0| 1343.0| 1457.0|
1584| 385.0| 348.0| -21.0| 2023.0| | 0.0| | 2034| 1700| 394.0| -9.0| 1658.0|SFO | 2565.0| 0.0|2018-12-31 02:00:00| | |UA |EWR | | 13.0| 33.0| | 1731.0| 2019.0|
4830| 119.0| 85.0| -35.0| 1431.0| | 0.0| | 1437| 1245| 136.0| -13.0| 1232.0|MSP | 546.0| 0.0|2018-12-31 02:00:00| | |OO |MSP | | 16.0| 18.0| | 1250.0| 1415.0|
2731| 158.0| 146.0| -19.0| 1911.0| | 0.0| | 1930| 1800| 160.0| -8.0| 1800.0|MSP | 842.0| 0.0|2018-12-31 02:00:00| | |WN |PVD | | 7.0| 7.0| | 1807.0| 1904.0|
```
Now that you have some sample data to play with, let’s see a decision tree example.
## Decision tree classification
Create a new virtual environment and activate it:
```bash
virtualenv env
source env/bin/activate
```
Install requirements:
```bash
pip install scikit-learn pandas scylla-driver
```
> To follow the code examples below you can either create a new python file or just use the Jupyter notebook that’s in the repo. If you use the notebook make sure the edit the `config.py` file with your credentials.
Connect to ScyllaDB:
```python
import pandas as pd
from sklearn.tree import DecisionTreeClassifier # Import Decision Tree Classifier
from sklearn.model_selection import train_test_split # Import train_test_split function
from sklearn import metrics #Import scikit-learn metrics module for accuracy calculation
from sqlalchemy import create_engine
from cassandra.cluster import Cluster, ExecutionProfile, EXEC_PROFILE_DEFAULT
from cassandra.policies import DCAwareRoundRobinPolicy, TokenAwarePolicy
from cassandra.auth import PlainTextAuthProvider
def pandas_factory(colnames, rows):
return pd.DataFrame(rows, columns=colnames)
def getCluster():
profile = ExecutionProfile(load_balancing_policy=TokenAwarePolicy(DCAwareRoundRobinPolicy(local_dc='AWS_US_EAST_1')),
row_factory=pandas_factory)
return Cluster(
execution_profiles={EXEC_PROFILE_DEFAULT: profile},
contact_points=[
""
],
port=9042,
auth_provider = PlainTextAuthProvider(username="scylla", password="******"))
cluster = getCluster()
session = cluster.connect()
```
Query data into a dataframe:
```python
query = "SELECT * FROM demo.flight_features;"
rows = session.execute(query)
df = rows._current_rows
```
Split the dataset into features and target variable:
Feature attributes:
* `actual_elapsed_time`
* `air_time`
* `arr_time`
* `crs_arr_time`
* `crs_dep_time`
* `crs_elapsed_time`
* `dep_time`
* `distance`
* `taxi_in`
* `taxi_out`
* `wheels_off`
* `wheels_on`
* `arr_delay`
Target attribute:
* `dep_delay`
```python
#Features
feature_cols = ["actual_elapsed_time", "air_time",
"arr_time", "crs_arr_time", "crs_dep_time",
"crs_elapsed_time", "dep_time", "distance", "taxi_in", "taxi_out",
"wheels_off", "wheels_on", "arr_delay"]
X = df[feature_cols]
y = df.dep_delay # Target variable
# Split dataset into training set and test set
X_train, X_test, y_train, y_test = train_test_split(X, y, test_size=0.3, random_state=1) # 70% training and 30% test
```
Create the classifier:
```python
# Create Decision Tree classifer object
clf = DecisionTreeClassifier()
# Train Decision Tree Classifer
clf = clf.fit(X_train,y_train)
#Predict the response for test dataset
y_pred = clf.predict(X_test)
print("Accuracy:",metrics.accuracy_score(y_test, y_pred))
Accuracy: 0.052884615384615384
```
Decision tree visualization in text form
```python
from sklearn.tree import export_text
tree_rules = export_text(clf, feature_names=feature_cols)
print(tree_rules)
```
```text
| | | | |--- taxi_in > 5.50
| | | | | |--- crs_arr_time <= 1307.50
| | | | | | |--- crs_dep_time <= 514.00
| | | | | | | |--- dep_time <= 501.00
| | | | | | | | |--- dep_time <= 272.50
| | | | | | | | | |--- class: 14.0
| | | | | | | | |--- dep_time > 272.50
| | | | | | | | | |--- class: -5.0
| | | | | | | |--- dep_time > 501.00
| | | | | | | | |--- class: -3.0
| | | | | | |--- crs_dep_time > 514.00
| | | | | | | |--- wheels_off <= 553.50
| | | | | | | | |--- crs_dep_time <= 536.50
| | | | | | | | | |--- wheels_on <= 745.50
| | | | | | | | | | |--- air_time <= 55.00
| | | | | | | | | | | |--- class: 6.0
| | | | | | | | | | |--- air_time > 55.00
| | | | | | | | | | | |--- truncated branch of depth 3
| | | | | | | | | |--- wheels_on > 745.50
| | | | | | | | | | |--- class: -2.0
| | | | | | | | |--- crs_dep_time > 536.50
| | | | | | | | | |--- class: -6.0
| | | | | | | |--- wheels_off > 553.50
| | | | | | | | |--- wheels_on <= 1257.00
| | | | | | | | | |--- taxi_out <= 12.50
| | | | | | | | | | |--- arr_delay <= -2.50
| | | | | | | | | | | |--- truncated branch of depth 5
| | | | | | | | | | |--- arr_delay > -2.50
| | | | | | | | | | | |--- truncated branch of depth 6
| | | | | | | | | |--- taxi_out > 12.50
| | | | | | | | | | |--- crs_elapsed_time <= 271.50
| | | | | | | | | | | |--- truncated branch of depth 11
| | | | | | | | | | |--- crs_elapsed_time > 271.50
| | | | | | | | | | | |--- truncated branch of depth 2
| | | | | | | | |--- wheels_on > 1257.00
| | | | | | | | | |--- class: 3.0
| | | | | |--- crs_arr_time > 1307.50
| | | | | | |--- crs_dep_time <= 1746.00
| | | | | | | |--- taxi_out <= 16.50
| | | | | | | | |--- crs_arr_time <= 1349.50
| | | | | | | | | |--- arr_delay <= -5.00
| | | | | | | | | | |--- class: 9.0
| | | | | | | | | |--- arr_delay > -5.00
| | | | | | | | | | |--- actual_elapsed_time <= 100.50
| | | | | | | | | | | |--- class: 10.0
| | | | | | | | | | |--- actual_elapsed_time > 100.50
| | | | | | | | | | | |--- truncated branch of depth 4
| | | | | | | | |--- crs_arr_time > 1349.50
| | | | | | | | | |--- wheels_on <= 1337.50
| | | | | | | | | | |--- class: -2.0
| | | | | | | | | |--- wheels_on > 1337.50
| | | | | | | | | | |--- taxi_in <= 15.50
| | | | | | | | | | | |--- truncated branch of depth 13
| | | | | | | | | | |--- taxi_in > 15.50
| | | | | | | | | | | |--- truncated branch of depth 6
| | | | | | | |--- taxi_out > 16.50
| | | | | | | | |--- crs_dep_time <= 1521.50
| | | | | | | | | |--- crs_dep_time <= 1105.00
| | | | | | | | | | |--- actual_elapsed_time <= 175.50
| | | | | | | | | | | |--- class: 5.0
| | | | | | | | | | |--- actual_elapsed_time > 175.50
| | | | | | | | | | | |--- truncated branch of depth 3
```
## Jupyter notebook
You can run and modify the classifier script using the Jupyter notebook file in the repository. Before running it locally, make sure to edit the `config.py` file with your proper (local or ScyllaDB Cloud) ScyllaDB configuration.
## Narrow table design
Here’s an example table definiton that uses narrow table design:
```sql
create table feature_store.flight_features_narrow (
OP_CARRIER_FL_NUM INT,
FL_DATE TIMESTAMP,
FEATURE_NAME TEXT,
FEATURE_VALUE FLOAT,
PRIMARY KEY (OP_CARRIER_FL_NUM)
)
```
In this example, you see just a few columns in the table. Aside from the
`OP_CARRIER_FL_NUM` and `FL_DATE` columns, which are specific to this example use case,
the two other columns are general feature columns that can be used to store
any number of different features in just two columns. This type of design is
more flexible and requires no schema changes in case of adding or removing features
from the database.
# used-cars-app.md
# Price prediction inference app
In this tutorial you’ll build a simplified feature store and real-time ML application
with ScyllaDB. App predicts used car prices based on the car’s features.
## Create a ScyllaDB cluster
In production, a ScyllaDB cluster should include at least three nodes. In this example, you’ll start with a single-node setup to keep things simple.
Start up a ScyllaDB node:
```default
docker run --name node1 --network scylla -p "9042:9042" -d scylladb/scylla-enterprise:2024.2 \
--overprovisioned 1 \
--smp 1
```
Check the status of your node:
```default
docker exec -it node1 nodetool status
```
The response you get back should be UN (Up and Normal). If it is not then wait a few seconds and try again as the node is not ready yet.
You should see something that looks like this:
```default
Datacenter: datacenter1
=======================
Status=Up/Down
|/ State=Normal/Leaving/Joining/Moving
-- Address Load Tokens Owns Host ID Rack
UN 172.17.0.2 204 KB 256 ? b26ab7f8-17ee-4e51-b28a-523697d16a60 rack1
```
---
## Create a feature store keyspace and tables
In this part, you’ll create a new keyspace and a new table.
Use cqlsh to interact with ScyllaDB:
```bash
docker exec -it node1 cqlsh
```
Create a keyspace called `feature_store`:
```default
CREATE KEYSPACE feature_store
WITH REPLICATION = {
'class' : 'NetworkTopologyStrategy',
'replication_factor' : 1
};
```
With this CQL command, you set the following replication strategy:
* `NetworkTopologyStrategy`: A production ready replication strategy that allows to set the replication factor independently for each data-center
* `replication_factor:`: The number of nodes that will store the same data. In production you’d set this to 3 or higher, to ensure that if one node becomes unavailable, you can still query your data using another node.
Activate the newly created keyspace:
```default
use feature_store;
```
Next, create a table `used_cars` with the following columns: model, year, price, fuel_type, brand:
```sql
CREATE TABLE used_cars (
car_id UUID,
model TEXT,
year INT,
price FLOAT,
brand TEXT,
PRIMARY KEY (car_id)
);
```
You can confirm that the table has been created by using the following CQL command:
```sql
DESC SCHEMA;
```
You can notice, that the table definiton has `car_id` as the PARTITION KEY. This allows efficient queries by the `car_id` column.
---
## Partition key, filtering
Insert two rows into the newly created table:
```sql
INSERT INTO used_cars(car_id, model, year, price, brand)
VALUES (70f6d200-e9fb-4765-af05-f5ef668e82ee, 'A6', 2022, 43950, 'Audi');
INSERT INTO used_cars(car_id, model, year, price, brand)
VALUES (9a0807eb-05df-47dc-9081-095f7881b470, 'Q5', 2024, 45300, 'Audi');
```
Now, read the table:
```sql
SELECT * FROM used_cars;
```
Query the table and add a `WHERE` clause:
```sql
SELECT * FROM used_cars WHERE car_id = 70f6d200-e9fb-4765-af05-f5ef668e82ee;
```
This query is using the `car_id` column in the `WHERE` clause. This query is efficient and scalable because `car_id` is a PARTITION KEY.
Let’s see what happens if you query by a non-PK column, `model`:
```sql
SELECT * FROM used_cars WHERE model = 'Q5';
```
You see an error message: `InvalidRequest: Error from server: code=2200 [Invalid query] message="Cannot execute this query as it might involve data filtering and thus may have unpredictable performance. If you want to execute this query despite the performance unpredictability, use ALLOW FILTERING"`.
What this means is that you tried to query by a non-PK column which would require a table scan and have unpredictable performance.
If you are willing to run a table scan, you can still execute the query using the `ALLOW FILTERING` extension:
```sql
SELECT * FROM used_cars WHERE model = 'Q5' ALLOW FILTERING;
```
What happens if you try to `INSERT` a new product with the same ID but different price?
```sql
INSERT INTO used_cars(car_id, model, year, price, brand)
VALUES (70f6d200-e9fb-4765-af05-f5ef668e82ee, 'A6', 2022, 39000, 'Audi');
```
```sql
SELECT * FROM used_cars WHERE car_id = 70f6d200-e9fb-4765-af05-f5ef668e82ee;
```
In this case, because the car_id already exists in the table, ScyllaDB will perform `UPDATE` instead of inserting a new row (executing an `UPSERT`, in other words).
---
## Clustering key
Now, let’s see how clustering keys help you access your data.
Create a new table, called `car_features`:
```sql
CREATE TABLE car_features (
car_id uuid,
feature_name text,
feature_value text,
PRIMARY KEY (car_id, feature_name)
);
```
Insert some sample data:
```sql
INSERT INTO car_features(car_id, feature_name, feature_value)
VALUES (8fb321c6-8ee0-4cd8-8568-3f149b7c298c, 'brand', 'Audi');
INSERT INTO car_features(car_id, feature_name, feature_value)
VALUES (8fb321c6-8ee0-4cd8-8568-3f149b7c298c, 'model', 'A1');
INSERT INTO car_features(car_id, feature_name, feature_value)
VALUES (8fb321c6-8ee0-4cd8-8568-3f149b7c298c, 'fuel_type', 'Diesel');
INSERT INTO car_features(car_id, feature_name, feature_value)
VALUES (8fb321c6-8ee0-4cd8-8568-3f149b7c298c, 'price', '14950');
```
This table contains features of used cars. Let’s breakdown the PRIMARY KEY:
* `car_id`: PARTITION KEY - allows efficient queries using the `car_id` column
* `feature_name`: CLUSTERING KEY - allows efficient queries using the `car_id` AND the `feature_name` columns
Query by `car_id` to fetch all the features for one car:
```sql
SELECT * FROM feature_store.car_features WHERE car_id = 8fb321c6-8ee0-4cd8-8568-3f149b7c298c;
```
By adding a CLUSTERING KEY, you can query one specific feature value, e.g. `model`:
```sql
SELECT * FROM car_features WHERE car_id = 8fb321c6-8ee0-4cd8-8568-3f149b7c298c AND feature_name = 'model';
```
Close cqlsh:
```sql
exit
```
## Real-time machine learning app example
In this part, you’ll set up a simplified machine learning app that predicts used car prices based on user input and a pre-trained model.
Connect to your ScyllaDB cluster using cqlsh and create the schema:
```bash
docker exec -it node1 cqlsh
```
```default
CREATE KEYSPACE IF NOT EXISTS feature_store WITH replication = {
'class': 'NetworkTopologyStrategy',
'replication_factor': 1
};
CREATE TABLE IF NOT EXISTS feature_store.car_features (
car_id uuid,
feature_name text,
feature_value text,
PRIMARY KEY (car_id, feature_name)
);
CREATE TABLE IF NOT EXISTS feature_store.raw_car_features (
car_id UUID,
brand TEXT,
model TEXT,
year INT,
transmission TEXT,
fuel_type TEXT,
mpg FLOAT,
engine_size FLOAT,
mileage INT,
tax FLOAT,
PRIMARY KEY (car_id)
);
```
Exit cqlsh:
```sql
exit
```
---
## Test the app
Create a new virtual environment in the app’s folder:
```bash
cd labs/used-cars-feature-store/
virtualenv env --python=python3.11 && source env/bin/activate
```
Install Python requirements (scikit-learn, scylla-driver, streamlit):
```bash
pip install scikit-learn scylla-driver streamlit
```
Use the `docker inspect -f '{{range .NetworkSettings.Networks}}{{.IPAddress}}{{end}}' node1` command to get the ScyllaDB HOST address.
```bash
NODE1=$(docker inspect -f '{{range .NetworkSettings.Networks}}{{.IPAddress}}{{end}}' node1)
echo $NODE1
```
Find the `config.py` file:
```python
SCYLLA_HOSTS = ["172.18.0.4"]
SCYLLA_KEYSPACE = 'feature_store'
SCYLLA_USER = 'scylla'
SCYLLA_PASS = ''
SCYLLA_DC = 'dc1'
```
Make sure the `HOST` value contains the output of:
```bash
echo $NODE1
```
If it doesn’t, fix it.
Run streamlit:
```bash
streamlit run app/app.py
```
Visit APP UI: http://localhost:8501
Hit `CTRL + C` to stop the server.
